AI BI governance prerequisites are the foundational conditions your data environment must satisfy before any AI analytics layer can return reliable, production-grade answers. Without them, your AI BI deployment will produce confident-sounding wrong answers — and your business users will stop trusting it within weeks. At Genloop, working across enterprise deployments from retail to finance, we have seen the same five missing prerequisites cause every pilot that looked promising in demo to collapse in production.
You have seen this play out. A vendor shows a polished demo: a business user types "What drove the revenue dip last Tuesday?" and the AI returns a clean, articulate answer in seconds. Your team is impressed. You approve a pilot. Eight weeks later, your VP of Sales is getting three different revenue figures depending on which question they ask, your analysts are losing trust in the tool, and your data team is fielding more questions than ever.
This is not a story about bad AI models. The models are fine. The problem is the data environment those models were dropped into.
According to the dbt Labs State of Analytics Engineering 2024 report, 72% of data teams say their biggest challenge with AI-augmented analytics is "inconsistent or undefined business logic" — not model quality, not latency, not cost. The bottleneck is governance. Specifically, the five prerequisites that almost every pilot skips because they feel like pre-work rather than the work itself.
This post is for BI architects and analytics leaders who are mid-pilot or mid-evaluation and are already experiencing reliability issues. We will name the prerequisites exactly, explain why each one breaks AI BI without it, and tell you what good looks like for each one.
Governance debt is not new. Your dashboards have been quietly lying for years — different filters applied here, a slightly different join there, a metric defined one way in Finance and another way in Marketing. Your analysts knew the quirks. They worked around them. Stakeholders trusted the dashboards because a human vouched for them.
AI removes the human vouching layer.
When an LLM queries your warehouse directly, it has no tribal knowledge. It does not know that rev_net means something different in the EMEA schema than in the US schema. It does not know that your CFO's definition of "active customer" excludes trial accounts but your growth team's definition includes them. It will pick one interpretation — confidently — and return a number. The business user has no way to know the number is wrong until something downstream breaks.
Gartner's research on analytics and BI platforms consistently finds that organisations without a governed semantic layer see AI query accuracy rates 40–60% lower than those with one in production. That gap does not close by tuning the model. It closes by fixing the prerequisites.
The governance debt your BI stack has been carrying silently becomes visibly catastrophic the moment AI touches it.
The single most common reason AI BI pilots fail is that there is no semantic layer — or the one that exists is undocumented, partial, or lives only in a BI tool the AI cannot access.
A semantic layer is the translation layer between your raw warehouse schema and the business concepts your users care about: revenue, churn, active users, cost per acquisition. Without it, the AI is reading raw table and column names and guessing what they mean. With it, the AI has a governed vocabulary it can resolve queries against reliably.
What good looks like: a semantic layer that is version-controlled, accessible via API or metadata catalog, and covers at minimum your top 20 most-queried business concepts with explicit join logic, filter logic, and business rules attached. It does not need to be perfect. It needs to exist and be readable by the AI layer.
In our experience deploying Genloop across enterprise data estates, teams that invest three weeks defining their semantic layer before activating conversational analytics see answer accuracy rates above 90% from day one. Teams that skip it spend months debugging one-off wrong answers instead.
"Everyone knows what revenue means." No, they do not. Your finance team means recognised revenue. Your sales team means booked ARR. Your growth team means gross transaction volume. All three are "revenue." All three will produce different numbers from the same AI query.
According to Monte Carlo Data's State of Data Quality 2024 report, 62% of data teams have experienced a significant business decision being made on incorrect data in the past year — and conflicting metric definitions are the leading root cause cited.
The prerequisite here is not a perfect metrics catalog. It is a decision: for each of your top 10 business metrics, there is one authoritative definition, it is written down, it is stored somewhere the AI layer can reference, and someone owns it.
What good looks like: a metrics catalog (even a well-maintained Notion doc or dbt metrics layer) that defines each metric with its formula, the table(s) it draws from, any filter or exclusion logic, and who approved it. The AI layer references this catalog — not the raw schema — when answering questions about that metric.
Pull up your warehouse schema right now. If you see columns named dt, cust_flg_v2, rev_adj_excl_rtn_B, or tables named staging_final_FINAL_use_this, your AI layer is going to struggle. Not because the AI is not smart enough — but because those names contain no semantic signal. They are abbreviations and conventions that exist only in the heads of the three people who built the pipeline in 2021.
The DAMA Data Management Body of Knowledge identifies schema naming consistency as a Tier 1 data quality dimension, directly correlated with downstream analytics reliability. When an AI layer encounters ambiguous naming, it either guesses — producing plausible-but-wrong answers — or refuses to answer, producing no value at all.
The fix is not renaming your entire warehouse. It is applying clear naming to the tables and columns your AI layer will actually query, prioritised by query frequency. Descriptive, unabbreviated column names. Consistent prefixes for dimension vs. fact tables. Clear date field naming. This work takes two to four weeks for a focused data engineer and pays dividends far beyond AI BI.
This prerequisite is the one practitioners on Reddit's r/BusinessIntelligence community flag most viscerally: "The AI gave a confident answer that was completely wrong and a director made a decision based on it." That is not an AI failure. That is a missing validation layer.
A validation layer means your AI BI system has a mechanism — automated or human — to cross-check its own outputs against known-good benchmarks before surfacing them to end users. This can be: automated query testing against a golden dataset, a confidence threshold below which the AI flags its answer as unverified, or a reconciliation step that compares AI-generated aggregates against your existing dashboard values.
In our experience, the most effective approach for early-stage AI BI deployments is a hybrid: automated sanity checks (does this revenue figure fall within ±5% of yesterday's dashboard value for the same period?) combined with visible reasoning transparency, so users can see the query path the AI took and catch logical errors before acting on them. Genloop surfaces this reasoning by default — every answer shows the SQL path taken, so a data-literate reviewer can spot a wrong join in seconds.
McKinsey research on data-driven enterprises finds that organisations with formal answer-validation processes in their AI analytics stacks are 2.4x more likely to report high trust in AI-generated insights among business users.
The final prerequisite is one that compliance and security teams flag — but that analytics leaders often underestimate until it becomes a crisis. If your access controls live only in your BI tool's UI (row-level security set in Tableau, column masking set in a dashboard filter), your AI layer bypasses them entirely when it queries the warehouse directly.
This means a business analyst who is legitimately restricted from seeing individual customer PII in a dashboard can ask the AI "show me all customer emails for accounts with revenue over $50K" and get a complete, unfiltered answer — because the AI is querying the warehouse directly, and the warehouse has no row-level security enforced at the data layer.
The prerequisite is data-layer access controls: row-level security, column-level security, and role-based access enforced in the warehouse itself (Snowflake, BigQuery, Databricks all support this natively), not just in the BI layer on top of it. Your AI layer should inherit and respect these controls automatically. If it does not — if your AI BI vendor cannot confirm that it reads warehouse-level permissions — that is a hard stop before production deployment.
| Dimension | Pilot Without Prerequisites | Pilot With Prerequisites |
|---|
| Answer accuracy at launch | 40–60% (Gartner benchmark) | 85–95% |
| Time to first business user trust | Never achieved | 2–4 weeks post-launch |
| Analyst burden | Increases (debugging AI errors) | Decreases (AI handles Tier 1 queries) |
| Governance debt exposure | Amplified and visible | Surfaced and resolved pre-launch |
| Compliance risk | High (UI-layer controls bypassed) | Low (warehouse-layer controls enforced) |
| Pilot outcome | Quietly shelved | Expanded to production |
The difference is not the AI vendor. It is the five weeks of governance work done before the AI is switched on.
Start with a one-week audit before your next pilot kick-off. For each prerequisite, ask a binary question:
- Semantic layer: Can I point the AI to a documented, API-accessible mapping of business concepts to warehouse objects? Yes or no.
- Metric definitions: Do I have a written, approved definition for our top 10 business metrics, with one owner per metric? Yes or no.
- Schema naming: Are the top 50 most-queried columns and tables named descriptively enough that an outsider could infer their meaning? Yes or no.
- Validation layer: Do I have a mechanism to catch wrong AI answers before they reach a director or executive? Yes or no.
- Access controls: Are my row-level and column-level security rules enforced at the warehouse layer, not just the BI tool UI? Yes or no.
Any "no" is a pre-condition to fix, not a "nice to have" for later. Prioritise them in the order listed — the semantic layer and metric definitions give you the most accuracy lift fastest.
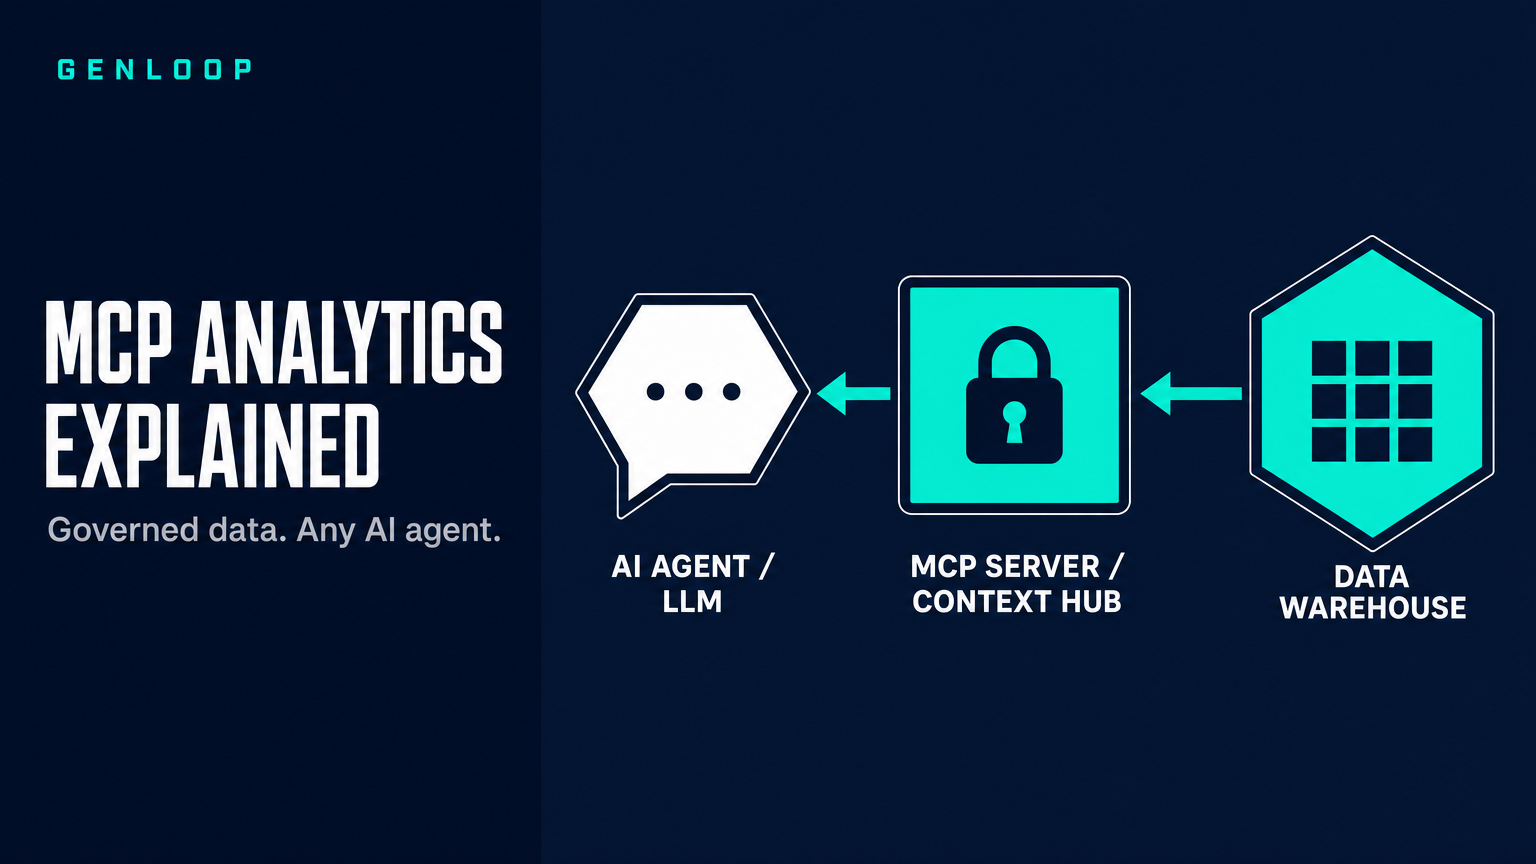
Genloop's Context Hub is designed to accelerate this process: it auto-discovers your schema, surfaces naming inconsistencies, and builds a living semantic layer that refines with every interaction. But it works best — and we are honest about this — when the governed metric definitions and warehouse-level access controls are already in place when you connect. The Context Hub does not replace governance. It amplifies it.
This post is not for analytics teams that are still evaluating whether to adopt AI BI at all. It is not for teams that have just connected a data source and run their first demo query. It is for teams that have already hit the production wall — the demos worked, the pilot stalled, and they suspect (correctly) that the problem is governance, not the AI vendor.
If your organisation has fewer than three structured data sources and a single analyst who owns all metric definitions, your governance prerequisites are likely already implicit and manageable. This framework is designed for organisations with multiple data sources, multiple teams with conflicting definitions, and a warehouse that has grown faster than the governance around it.
The AI BI demos will keep getting better. The models will keep improving. But none of that matters if your production deployment is returning confident wrong answers because a semantic layer does not exist, metric definitions live in someone's head, and access controls stop at the dashboard UI.
The five prerequisites — semantic layer, governed metric definitions, schema naming conventions, validation layer, and warehouse-level access controls — are the unglamorous work that determines whether your AI BI investment delivers ROI or erodes trust.
If you want to see what a governed AI analytics deployment looks like before you rebuild your stack, explore Genloop at genloop.ai. We are direct about what we need from your environment to make it work — because the last thing either of us needs is another pilot that looks good in demo and breaks in production.
AI BI governance prerequisites are the foundational data environment conditions required for an AI analytics layer to return accurate, trustworthy answers in production. They include a semantic layer mapping business concepts to warehouse objects, governed metric definitions with a single authoritative owner, consistent schema naming conventions, a validation layer to catch incorrect AI outputs, and warehouse-level access controls enforced at the data layer. Without these in place, AI BI tools produce plausible-sounding answers that are factually unreliable.
For most enterprise teams with an existing data warehouse, a focused governance sprint takes four to six weeks. The semantic layer and metric definitions typically take two to three weeks; schema normalisation for the top queried tables takes one to two weeks; and access control auditing takes three to five business days if warehouse-layer permissions are already partially configured. Teams that skip this sprint and launch AI BI without prerequisites typically spend three to six months debugging unreliable answers instead.
AI BI demos are almost always run against a clean, curated dataset with pre-defined business logic baked in by the vendor. Production environments have messy schema naming, conflicting metric definitions across teams, and access controls that live only in the BI UI layer. The AI model has no tribal knowledge of these inconsistencies — it reads raw schema and guesses. According to Gartner, organisations without a governed semantic layer see AI query accuracy rates 40–60% lower than those with one in production, a gap that closing requires governance work, not model tuning.
A semantic layer is the technical translation layer that maps raw warehouse tables and columns to business-readable concepts and defines how they join and filter. A metrics catalog is the business governance layer that defines what each metric means, its formula, its owner, and any exclusion logic. Both are required for production AI BI. The semantic layer tells the AI how to query the data; the metrics catalog tells it what the answer should represent. Many teams have one but not the other — and accuracy breaks down without both.
Genloop works best when warehouse-level access controls and core metric definitions are already in place, but its Context Hub is specifically designed to accelerate the semantic layer build. It auto-discovers your schema, surfaces naming inconsistencies, and refines its understanding with every interaction. For teams mid-pilot with partial governance, Genloop can be deployed in a scoped context — a single domain, a single team's metrics — while governance prerequisites are built in parallel. We are direct about this trade-off in every evaluation conversation.