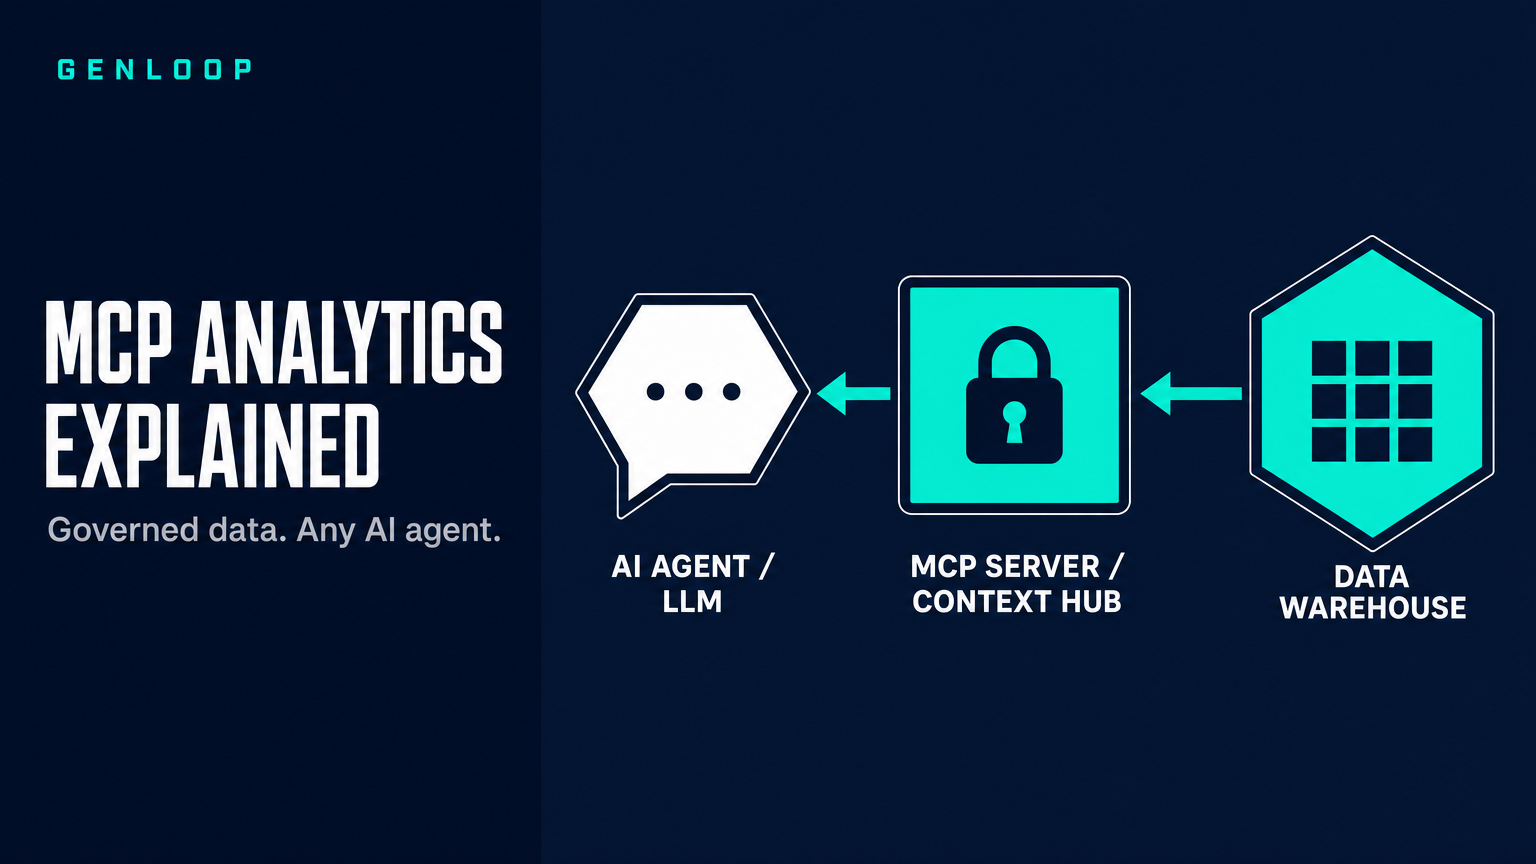
Conversational BI is the practice of querying business data in plain English and receiving governed, accurate answers—without writing SQL or navigating dashboards. The promise is self-serve analytics for every team member, not just analysts. But the reliability of any conversational BI tool is not determined by how fast it generates SQL. It is determined by whether the system understands what your metrics actually mean before it writes a single query. Genloop's Living Context Graph is built on exactly this principle: semantic understanding first, SQL generation second.
You already know the pitch. Ask your data a question in plain English, get an answer in seconds. No SQL. No ticket. No waiting. Conversational BI tools have been making this promise for three years, and evaluating whether they actually deliver it in production is now one of the most consequential decisions a BI leader makes.
The problem is that most vendor content glosses over the hard part. Practitioners on Reddit and in analytics engineering communities are consistently blunt about it: the bottleneck is not SQL generation speed. It is metric semantic consistency — the question of whether the system and your team agree on what "revenue," "active user," or "churn" actually means before the query runs.
This post is for BI directors, analytics engineers, and data leaders who are past the demo stage and need a clear framework for evaluating whether a conversational BI tool is production-ready — or just fast at generating wrong answers confidently.
The dominant narrative in conversational BI marketing is that LLMs have finally gotten good enough at text-to-SQL to make natural language queries reliable. This framing misidentifies the bottleneck.
SQL generation quality has improved dramatically. GPT-4 class models can produce syntactically correct SQL for moderately complex queries at a rate that would have seemed impossible in 2022. According to a 2024 evaluation by dbt Labs, the majority of analytics engineering teams now consider LLM-assisted SQL generation "good enough for simple to intermediate queries." That threshold was crossed. It is no longer the hard problem.
The hard problem is that SQL correctness and answer correctness are not the same thing. A query can execute without error and return a number that is completely wrong relative to what the business user actually asked. This happens when the system does not know that your "monthly recurring revenue" excludes trial conversions, that "active users" means 30-day window not 7-day, or that "region" in the sales table maps differently from "region" in the ops table. Those are semantic problems, not syntactic ones.
In our experience working with enterprise data teams, this is where almost every "AI chat bolted onto dashboards" deployment breaks down within 90 days of production rollout. The demo works because the demo uses clean, labeled, unambiguous data. Production fails because production data has history, exceptions, and contested definitions that accumulate over years.
Semantic sprawl is the condition where the same metric name means different things across different teams, dashboards, or data models. It is not a new problem — it predates conversational BI by a decade. But conversational AI tools make it acutely dangerous because they surface the inconsistency to every user, not just the analyst who knows which version of the metric to trust.
According to McKinsey's research on data-driven enterprises, organizations that lack a governed metric layer spend an estimated 30–40% of analytics time resolving conflicting data definitions rather than acting on insights. That cost was manageable when data access was gated through a small analyst team. It becomes catastrophic when a VP of Sales, a Finance lead, and a Marketing director are all asking the same AI tool the same revenue question and getting three different answers.
The cold-start problem compounds this. Most conversational BI tools require significant data engineering investment upfront to build the semantic context that makes queries reliable — mapping tables, defining joins, annotating columns, establishing metric hierarchies. For enterprises with large SQL estates (hundreds of tables, dozens of data sources), this setup can take months. Gartner's Augmented Analytics Market Guide notes that semantic layer maintenance is one of the top three reasons enterprise BI deployments stall before reaching production readiness.
This is where the governance-before-AI principle matters. A governed semantic layer is not a feature you add after the AI works. It is the precondition for the AI working at all.
| Dimension | SQL Generation Speed (vendor default focus) | Governed Semantic Layer (production-ready focus) |
|---|
| What it optimizes | Query execution time, NL2SQL accuracy | Metric definition consistency across all users |
| Where it breaks | Complex multi-table joins, ambiguous schema | Contested metric definitions, cold-start setup |
| Primary beneficiary | Demo environments, single-source queries | Enterprise teams with multiple data sources |
| Governance model | Post-hoc (review after answer is wrong) | Pre-hoc (definitions locked before query runs) |
| Context retention | Stateless — resets each session | Stateful — refines with every interaction |
| Time to production trust | Fast to demo, slow to trust | Slower to deploy, faster to trust |
| Error surface | Syntactic SQL errors | Semantic answer errors |
Genloop's approach prioritizes the right column. The Living Context Graph auto-discovers schema, ingests business documents and glossaries, and refines its understanding of your metrics with every interaction — without requiring a data engineering sprint to set it up manually. In our experience deploying with enterprise clients including global retail operators and financial services firms, this self-learning semantic layer cuts the time to production trust by more than half compared to tools that require full manual semantic layer configuration upfront.
BI practitioners on forums like Reddit's r/BusinessIntelligence are consistently more skeptical of conversational BI claims than vendor content would suggest. The pattern is consistent: practitioners who have tried deploying these tools in production report that the first-query demo quality does not hold under real-world conditions. The specific failure modes they cite are not SQL errors — they are semantic errors. "It confidently returned a number for 'churn' that didn't match our definition because our churn definition has three edge cases that aren't in the schema."
This skepticism is a useful calibration tool. It points directly at what to evaluate in a vendor proof-of-concept: not whether the tool can answer a clean question correctly, but whether it handles your definition of "revenue" consistently across 20 different phrasings, from five different users, across three months of interaction history.
MIT Sloan research on AI project failures at the data layer found that 62% of failed enterprise AI deployments cited data quality and consistency issues — not model capability — as the primary cause. Conversational BI is not immune to this pattern. The tools that survive production are those that treat semantic governance as a first-class engineering problem, not a configuration afterthought.
The differentiation Genloop makes against tools like Databricks Genie, ThoughtSpot, and Qlik is precisely here. Those tools are strong on SQL generation and visualization. The question is whether they carry the semantic context of your business in a form that evolves, governs, and explains itself — or whether they require your data engineering team to maintain that context manually in perpetuity.
Evaluating conversational BI tools for production requires testing against your hardest semantic problems, not your easiest ones.
Start with your three most contested metric definitions — the ones where Finance and Sales would give different answers. Ask the tool each metric across at least five different phrasings. If the answers are consistent, that is a signal the semantic layer is doing its job. If the answers vary by phrasing, the system is resolving ambiguity at query time rather than at definition time — which means every user is getting a slightly different version of the truth.
Test context retention across a session. Ask a follow-up question that requires remembering what was established three questions earlier. Stateless systems will fail this test or require the user to re-specify context. Stateful systems — those that maintain a living context graph — will carry the established context forward without prompting.
Evaluate the governance model. Ask the vendor specifically: where do metric definitions live, who can modify them, and how does the system handle a conflict between a user's phrasing and the governed definition? The answer reveals whether governance is a first-class architecture decision or a post-hoc filter.
Finally, evaluate answer transparency. Production-ready conversational BI should be able to show the reasoning path — not just the answer, but which tables were joined, which definition of the metric was applied, and why. Genloop surfaces this reasoning by default, which is what makes it auditable in regulated industries and trustworthy in organizations where data trust is still being established.
This post — and Genloop as a platform — is not the right fit for teams that are still in the process of establishing basic data warehouse hygiene. If your tables are undocumented, your joins are unmapped, and your metric definitions have never been written down anywhere, a conversational BI tool will accelerate your metric chaos, not resolve it. Similarly, if your primary need is a visualization layer for a single, clean, well-governed data source, a traditional BI tool may be more appropriate than a conversational AI platform.
Conversational BI reliability is a governance problem disguised as a technology problem. The teams getting durable value from natural language analytics are not the ones who found the fastest NL2SQL engine. They are the ones who resolved metric definitions, established a governed semantic layer, and then let AI surface that governed knowledge to every user simultaneously.
Genloop is built for teams that are ready to make governance the foundation, not the retrofit. If you're evaluating whether your organization is ready to move conversational analytics from proof-of-concept to production, the place to start is your semantic layer — not your SQL benchmark.
See how Genloop's Living Context Graph handles your metric definitions → genloop.ai
Conversational BI is an analytics approach that allows users to query business data using plain English questions instead of SQL queries or dashboard navigation. Traditional BI tools like Power BI or Tableau require users to know where data lives and how to navigate pre-built reports. Conversational BI removes that requirement — but reliability depends entirely on whether the underlying system has a governed semantic layer that understands your business's specific metric definitions, not just your database schema.
A governed semantic layer stores your organization's metric definitions — what "revenue," "churn," or "active user" means specifically for your business — and enforces those definitions before any query runs. Without it, conversational BI tools resolve ambiguous questions at query time, meaning different phrasings return different numbers for the same metric. With a governed layer, the definition is locked upstream, so every user gets a consistent answer regardless of how they phrase the question. This is the difference between a tool that is fast and one that is trustworthy.
Setup time varies significantly by approach. Tools that require manual semantic layer configuration — annotating every table, column, and metric relationship — can take two to six months for large SQL estates. Platforms like Genloop that use a self-learning context graph can auto-discover schema and ingest existing business documentation, reducing time to initial production readiness to days or weeks. However, full production trust — where the system reliably handles your most complex and contested metric definitions — typically requires one to three months of iterative refinement regardless of platform.
Direct LLM-to-database access via tools like GPT-4 with a database plugin generates SQL but has no persistent understanding of your business's metric definitions, governance rules, or context from previous queries. Every session starts from scratch. Purpose-built conversational BI platforms maintain a stateful semantic layer, enforce role-based data access controls, retain context across sessions, and provide answer transparency — showing which definition was applied and why. For one-off exploratory queries, direct LLM access may suffice. For production analytics at scale, governance and context retention are non-negotiable.
Conversational BI delivers the highest value for organizations where analyst bottlenecks are slowing business decisions — specifically Finance, Marketing, Sales Operations, and Product teams where non-technical leaders need frequent answers to data questions but cannot or should not be writing SQL. It is most effective when the data team has already established basic data warehouse hygiene and is ready to encode metric definitions into a governed semantic layer. BI directors and analytics engineers evaluating production readiness should prioritize teams with high-frequency ad-hoc data needs and clear, documentable metric definitions as the first deployment candidates.